
Neural operators and residual correction
Python implementations of neural operators and the residual-correction schemes, with the notebooks used to test them
A neural operator learns the map from a PDE’s parameters to its solution. Once trained, evaluating it costs a small fraction of what the solver costs. That changes what is affordable for anything needing the same equation solved thousands of times: inference, optimization, design.
The difficulty is that a trained surrogate carries no indication of when it is wrong. A small average error on held-out data does not bound the error on the single input an optimizer is about to query. That is the gap this project works on: not accuracy alone, but a surrogate that can report and then repair its own error.
The move that makes this tractable is to stop treating the surrogate’s output as an answer and start treating it as a guess to be checked. Substitute it into the governing equations and the residual tells you how badly they are violated, without needing the true solution. Better, under the stability assumptions the method rests on, that residual can be turned into a correction: solve one linear variational problem and add the result. The correction replaces a fresh nonlinear solve with a single linear one, and it is derived from the physics rather than learned from more data.
Applied to a corrector operator with PCANet-type surrogates, this cut solution error by close to two orders of magnitude in the cases tested. The consequence that matters is downstream: in topology optimization, optimizers driven by an uncorrected surrogate made errors as high as 80 percent: not small errors in the field, but the wrong design. With the correction the same optimizers landed below 7 percent.
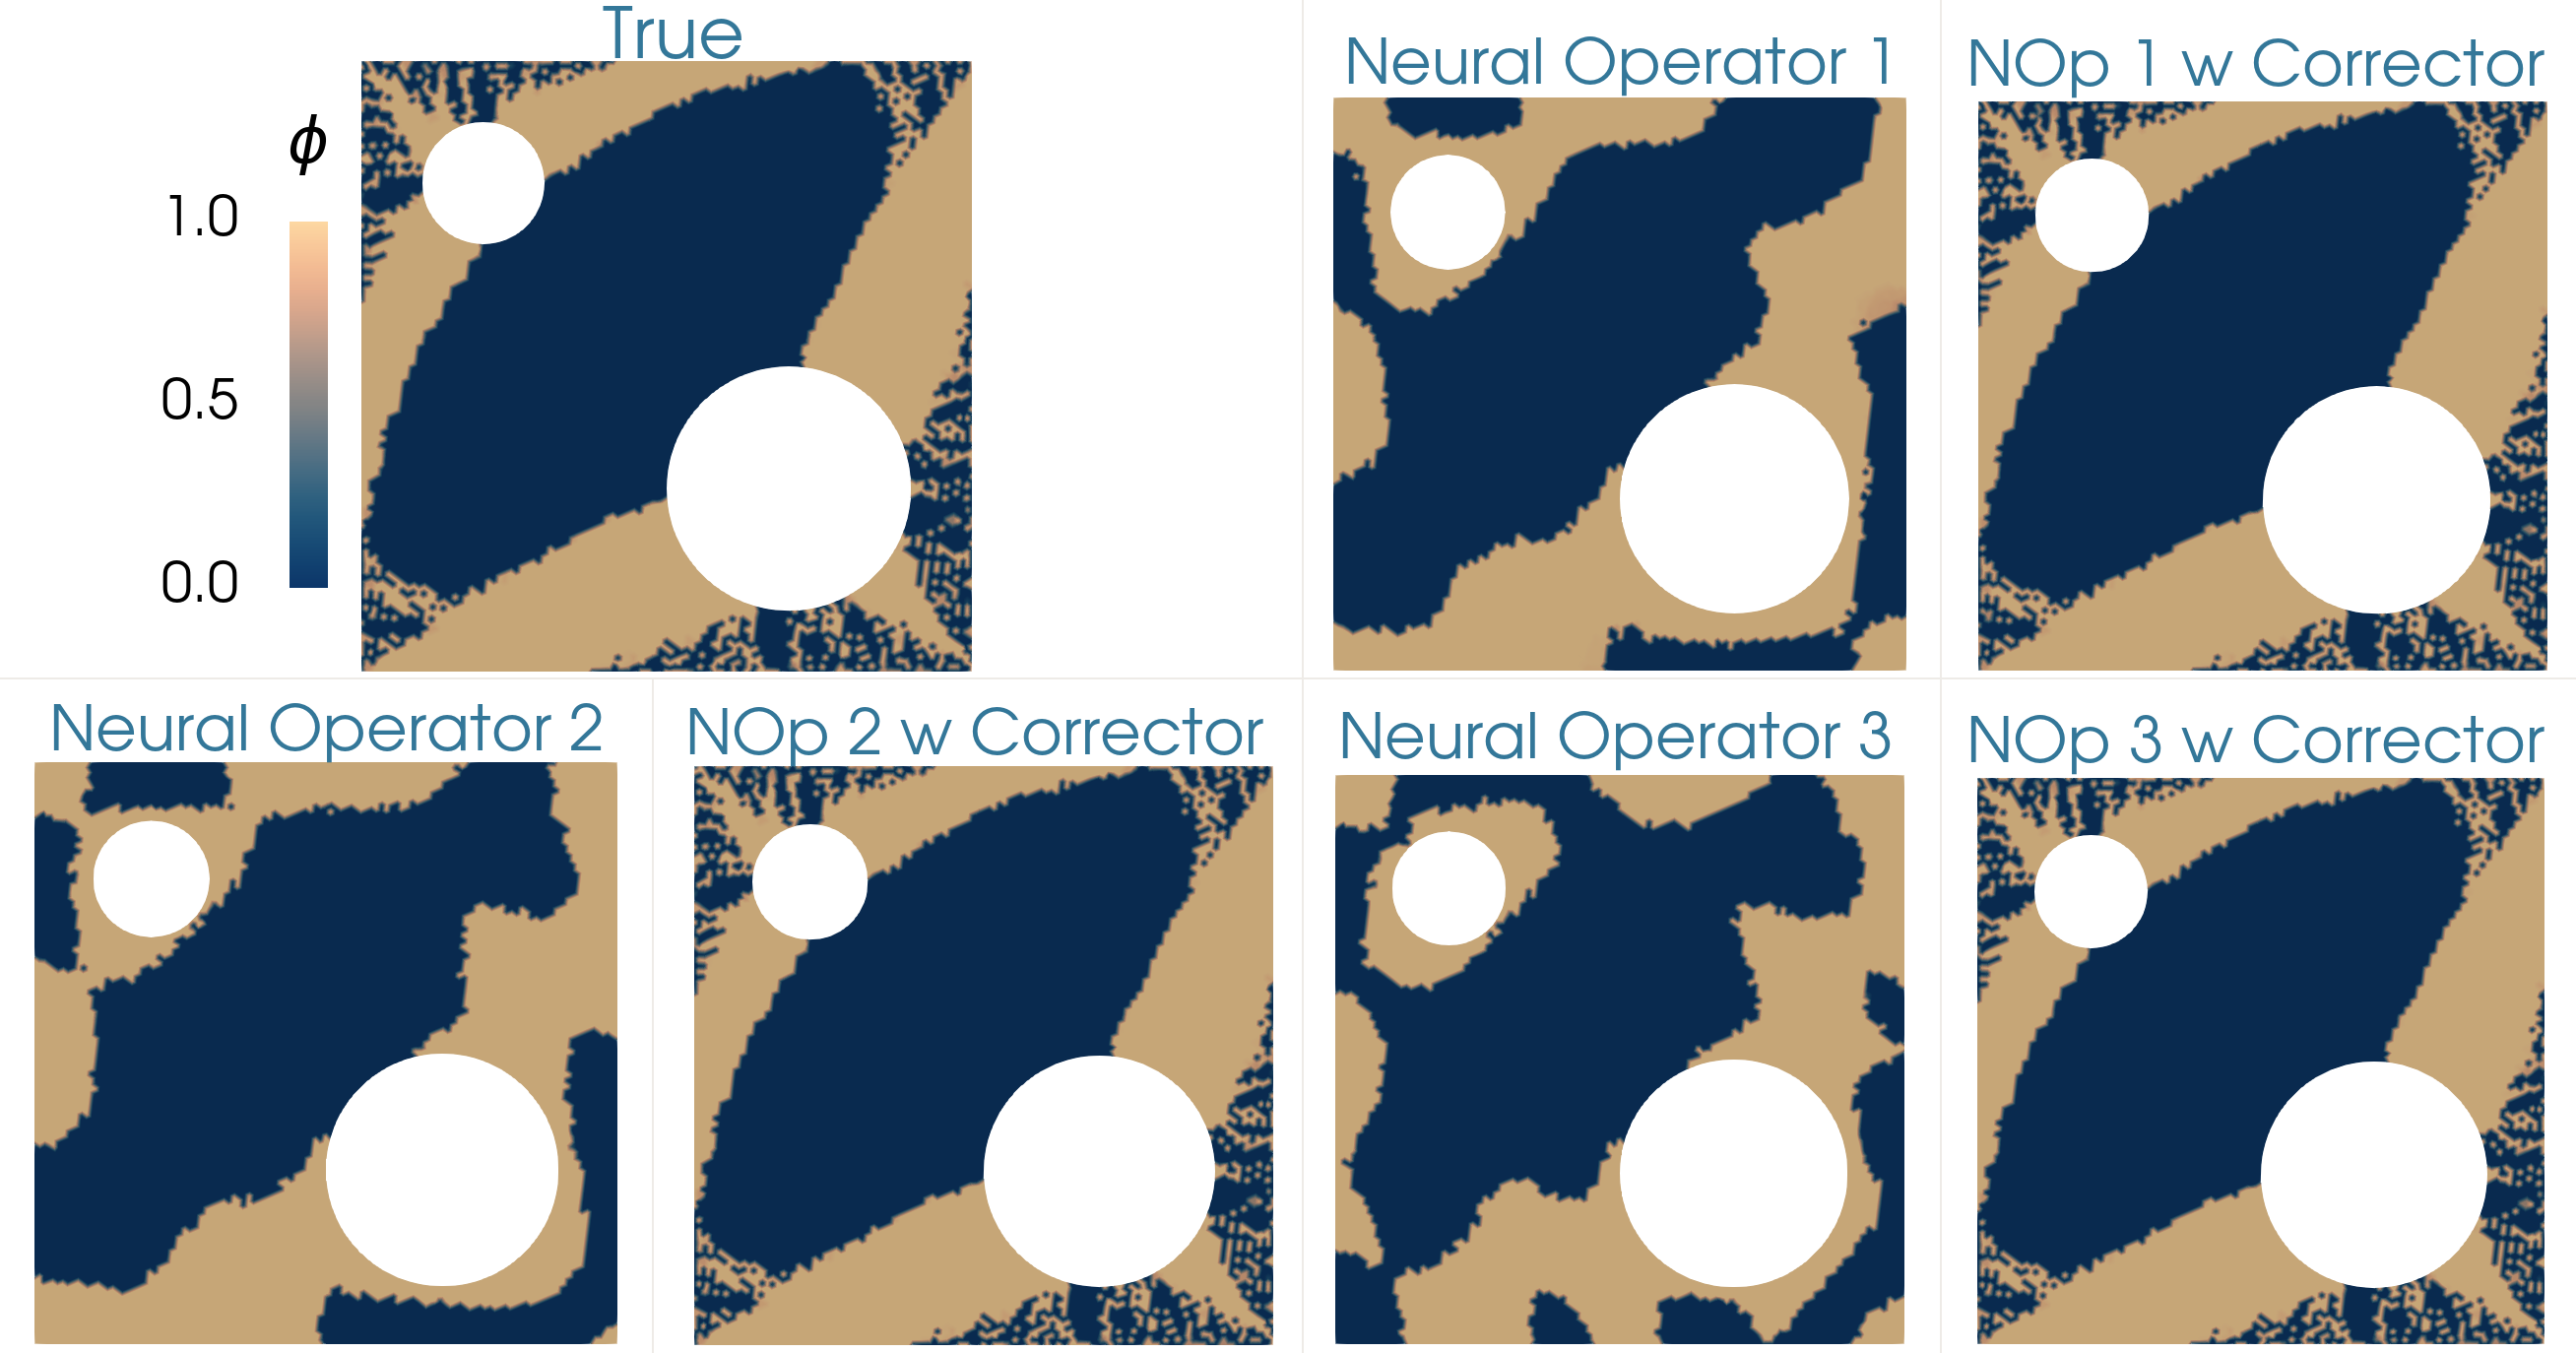
Bayesian inverse problems are the harder test, because errors do not stop at the answer. They propagate into a posterior, and a biased posterior is worse than an uncertain one. The study with Lianghao Cao, Thomas O’Leary-Roseberry, Tinsley Oden and Omar Ghattas showed that correcting a trained neural operator in this way achieves a quadratic reduction in approximation error while keeping most of the sampling speedup, on a nonlinear reaction–diffusion problem and on deformation of hyperelastic materials. Cao et al. (2023), in JCP.
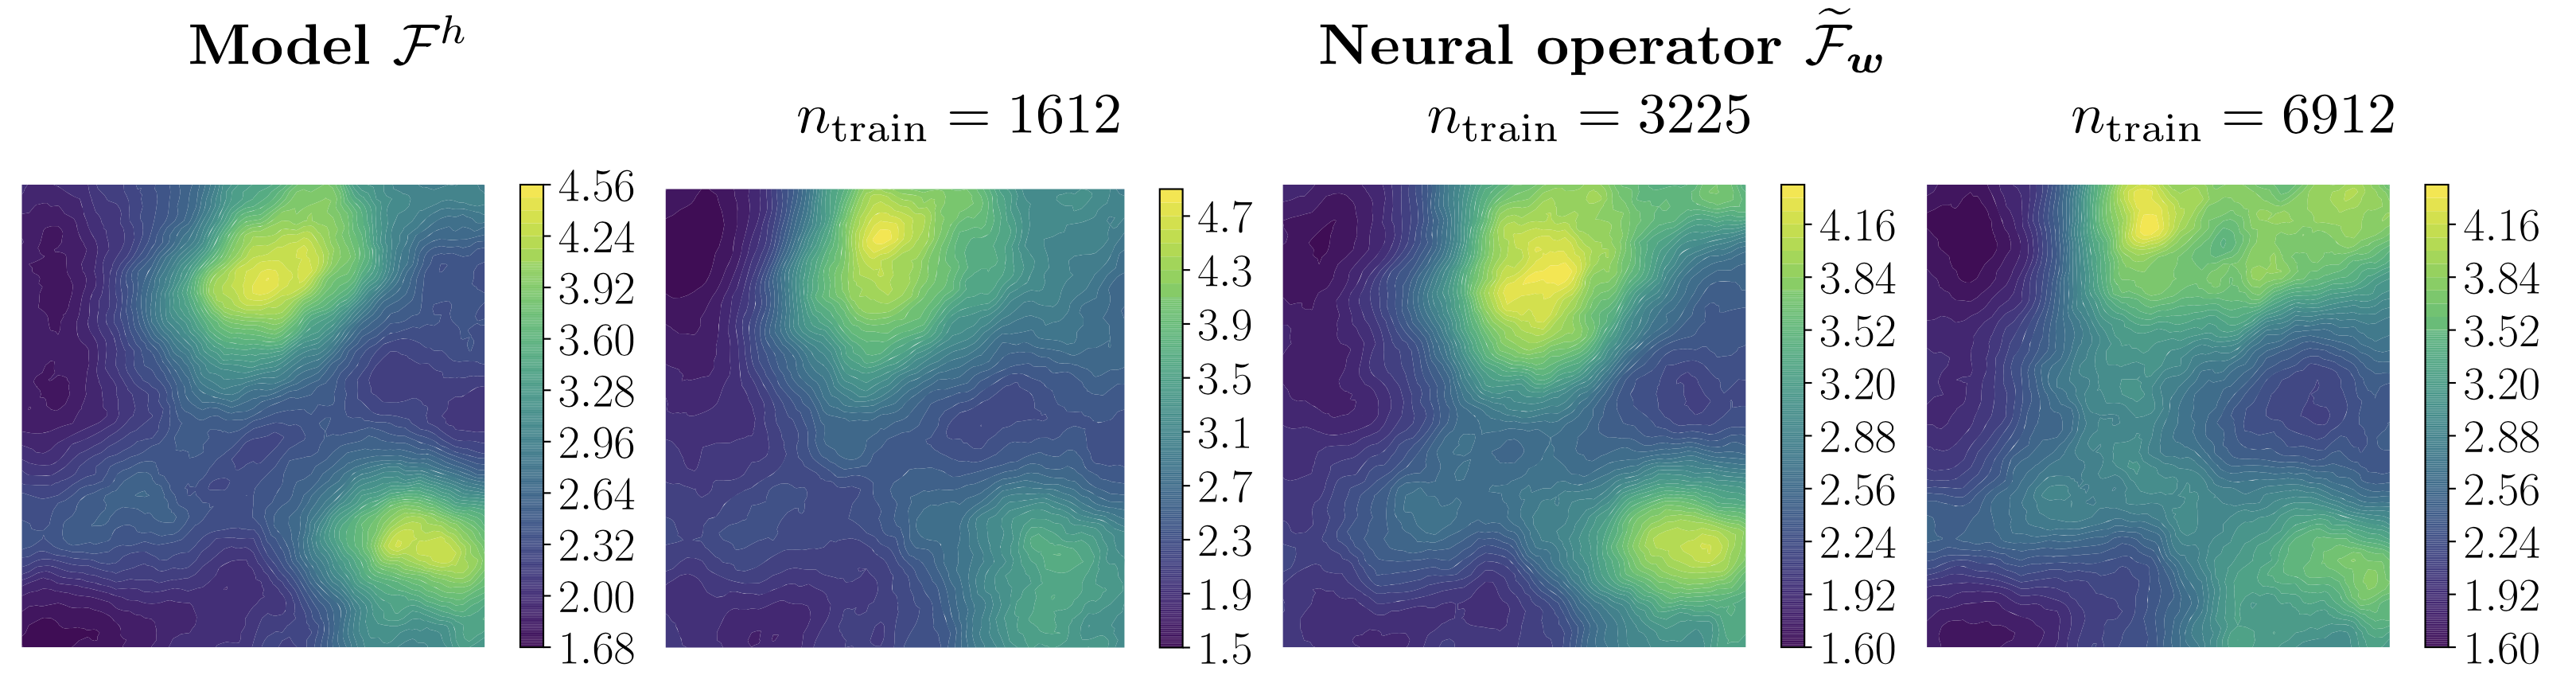
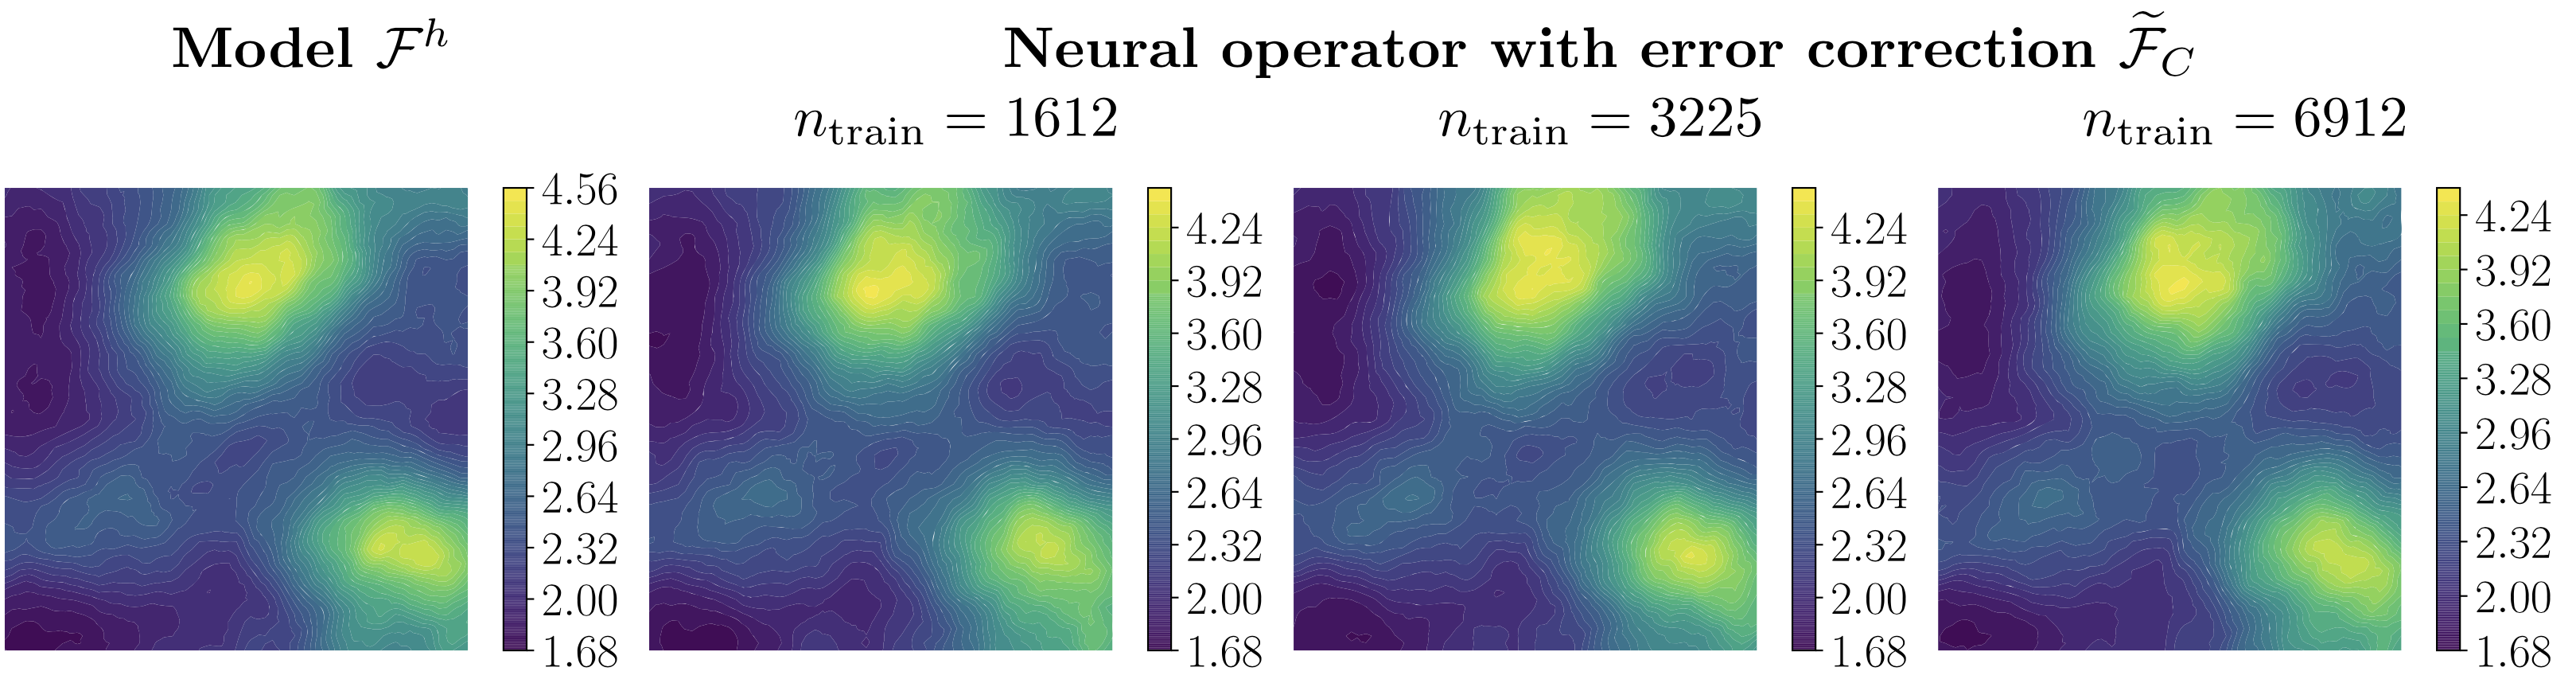
Underneath both results is an older idea, developed with Tinsley Oden: model error should be measured against the quantity of interest, not in a generic norm. A model can be badly wrong in ways that do not move the number you intend to act on, and nearly right in ways that do. Estimating error goal-oriented in this sense turns out to be usable for inference as well as for adaptivity: it lets a low-fidelity model with known parameters say something about a high-fidelity system whose parameters are not known. Jha and Oden (2022), in JCP.
Correcting every prediction is safe and wasteful. Most of the time the surrogate is fine; occasionally it is badly wrong; and the residual is a cheap signal for telling those cases apart. The direction now is a policy that decides per query whether to accept the surrogate, correct it, or fall back to a full solve, so the computational budget goes where the error would have changed a decision.
A supervised prototype of that selector exists, including a spectral-feature three-action variant. A broader learned controller is a proposed direction, not a demonstrated result, and end-to-end timings have not yet been reconciled. There is a survey of the practical landscape and a book chapter on the correction methods.
Whether that carries into design is the question magnetic soft material design is set up to answer: can these surrogates absorb the repeated forward solves without changing the design that comes out the other end?
Python implementations of neural operators and the residual-correction schemes, with the notebooks used to test them
Bayesian calibration and model comparison for a continuum SEIRD epidemic model.